IntroductionFor this homework, you will implement a naive Bayes classifier that estimates its parameters from training material in order to classify the unseen instances in test material. You will also extract features from data instances to improve classification accuracy.To complete the homework, download the tarball containing the stub programs and data. Your submission will be:
Tip: Look over the entire homework before starting on it. Then read through each problem carefully, in its entirety, before answering questions and doing the implementation. Finally: if possible, don't print this homework out! Just read it online, which ensures you'll be looking at the latest version of the homework (in case there are any corrections), you can easily cut-and-paste and follow links, and you won't waste paper. Problem 1 - A good day to play tennis? [10 pts]Let’s start with a simple example problem from Tom Mitchell’s book Machine Learning.
The problem is to predict whether it is a good day to play tennis given
various factors and some initial data that provides information about
whether previous days were good or bad days for tennis. The factors
include (in the format "Attribute: <List of Possible Values>"):
Each row in the data files corresponds to a single classification instance. For example, here is the training set. classify/data/tennis/train Outlook=Sunny,Temperature=Hot,Humidity=High,Wind=Weak,No Outlook=Sunny,Temperature=Hot,Humidity=High,Wind=Strong,No Outlook=Overcast,Temperature=Hot,Humidity=High,Wind=Weak,Yes Outlook=Rain,Temperature=Mild,Humidity=High,Wind=Weak,Yes Outlook=Rain,Temperature=Cool,Humidity=Normal,Wind=Weak,Yes Outlook=Rain,Temperature=Cool,Humidity=Normal,Wind=Strong,No Outlook=Overcast,Temperature=Cool,Humidity=Normal,Wind=Strong,Yes Outlook=Sunny,Temperature=Mild,Humidity=High,Wind=Weak,No Outlook=Sunny,Temperature=Cool,Humidity=Normal,Wind=Weak,Yes Outlook=Rain,Temperature=Mild,Humidity=Normal,Wind=Weak,Yes Outlook=Sunny,Temperature=Mild,Humidity=Normal,Wind=Strong,Yes Outlook=Overcast,Temperature=Mild,Humidity=High,Wind=Strong,Yes Outlook=Overcast,Temperature=Hot,Humidity=Normal,Wind=Weak,Yes Outlook=Rain,Temperature=Mild,Humidity=High,Wind=Strong,No Each instance consists of a list of attribute values, separated by commas, and the last element is the classification value. The value is "Yes" if it is a good day to play tennis based on the conditions, and "No" if it is not. What we are interested in for this toy example is to determine whether the probability of playing tennis is higher than the probability of not playing tennis. We can represent the probability of playing tennis as: 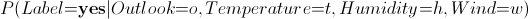 Note that Label, Outlook, Temperature, Humidity, and Wind are all random variables, yes is a value, and o, t, h, and w are variables for values. In order to reduce clutter, we'll write expression without explicit random variables, so the above will be written just as: 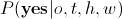 So, we want to find out whether: 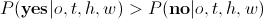 Another way of stating this is that for each instance (with values for o, t, h, and w ), we seek to find the label x with maximum probability: 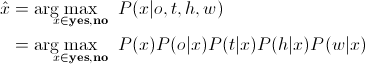 Part (a) [4 pts]. Written answer. Show explicitly how the last line above is derived from the first line using Bayes rule, the chain rule, independence assumptions, and from the fact we are finding the argmax. So, if we have a new instance that we wish to classify, like: Outlook=Sunny,Temperature=Cool,Humidity=High,Wind=Strong what we seek is: 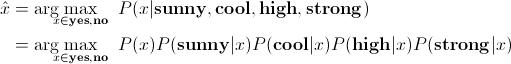 This simply means we need to compute the two values: 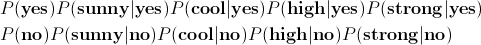 And pick the label that produced the higher value. Terms like P(yes) and P(sunny|no) are just parameters that we can estimate from a corpus, like the training corpus above. We'll start by doing maximum likelihood estimation, which means that the values assigned to the parameters are those which maximize the probability of the training corpus. We'll return to what this means precisely later in the course; for now, it just means that you do exactly what you'd think: count the number of times (frequency) each possibility happened and divide it by the number of times it could have happened. Here are some examples: 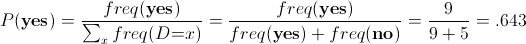 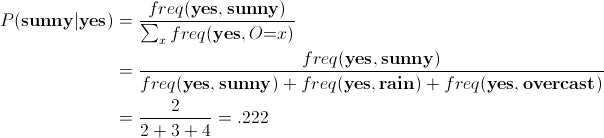 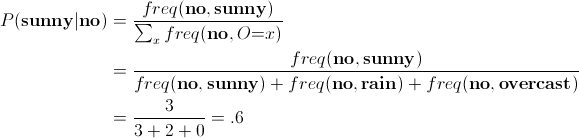 The data includes a test set for the tennis task as well, provided in full here: classify/data/tennis/test Outlook=Sunny,Temperature=Cool,Humidity=High,Wind=Strong,No Outlook=Overcast,Temperature=Cool,Humidity=Normal,Wind=Weak,Yes Outlook=Sunny,Temperature=Hot,Humidity=Normal,Wind=Weak,Yes Outlook=Rain,Temperature=Hot,Humidity=High,Wind=Strong,No Outlook=Sunny,Temperature=Cool,Humidity=Normal,Wind=Weak,Yes Outlook=Overcast,Temperature=Hot,Humidity=High,Wind=Strong,No Outlook=Sunny,Temperature=Mild,Humidity=High,Wind=Weak,Yes Outlook=Overcast,Temperature=Mild,Humidity=Normal,Wind=Strong,Yes Outlook=Rain,Temperature=Cool,Humidity=Normal,Wind=Strong,No Outlook=Overcast,Temperature=Cool,Humidity=Normal,Wind=Strong,Yes Outlook=Rain,Temperature=Hot,Humidity=Normal,Wind=Weak,Yes Outlook=Sunny,Temperature=Cool,Humidity=High,Wind=Weak,Yes Outlook=Rain,Temperature=Hot,Humidity=Normal,Wind=Strong,No Like the training set, this provides a list of instances, and for each instance, the values for each of the attributes and the classification outcome. Part (b) [2 pts]. Written answer. Using the training set to determine the relevant parameters, what is the most probable label for: Outlook=Sunny,Temperature=Hot,Humidity=Normal,Wind=Weak Make sure to show your work, including the values you obtained for each label. Does it match the label given for the third instance in the test set above? Part (c) [3 pts]. Written answer. Derive the general formula for calculating P(x|o,t,h,w) and calculate P(yes|overcast,cool,normal,weak) based on parameters estimated from the training set. Part (d) [1 pt]. Written answer. Provide a set of attribute values o, t, h, and w for which the probability of either yes or no is zero. Problem 2 - Implement basic naive Bayes [25 pts]Implementation. Complete the stub program classify/tennis_cat.py
so that it learns parameters from the training set, calculates the
scores for each label for each instance in the test set, and then
outputs the probabilities for each label in reverse sorted order, using
the format:Label_1 Probability_1 Label_2 Probability_2 ... Label_n Probability_n For example, here's what the output should look like: No 0.795417348609 Yes 0.204582651391 Yes 1.0 No 0.0 Yes 0.672947510094 No 0.327052489906 No 0.8382923674 Yes 0.1617076326 ... See the instructions in the stub program for specific places to make changes to do this implementation. Note: if the score for all labels is zero (remember we aren't smoothing yet), you should output a uniform distribution in which all labels receive the probability 1.0/number_of_labels. This won't happen for the tennis data set, but will happen for the prepositional phrase attachment data in the next problem. Before you get started, tennis_cat.py doesn't do what it is supposed to do, but you can run it (in the classify directory) with verbose output to start developing and debugging: $ ./tennis_cat.py --train data/tennis/train --predict data/tennis/test --verbose Showing verbose output. Frequency accumulation for labels not implemented yet. Frequency accumulation for (attr,val) and (attr,val,label) not implemented yet. ... It's up to you to fill in the required capabilities! When you are done, you should be able to run the program as follows: $ python tennis_cat.py --train data/tennis/train --predict data/tennis/test --out predictions.txt To see the accuracy of the predictions against the gold standard labels in the test file, do the following: $ python score.py --gold data/tennis/test --predict predictions.txt You should see the following output: Accuracy: 61.54 Tip: things are set up so that:
$ python tennis_cat.py -t data/tennis/train -p data/tennis/test | python score.py -g data/tennis/test Also, you can run without calling Python explicitly as follows: $ ./tennis_cat.py -t data/tennis/train -p data/tennis/test | ./score.py -g data/tennis/test Tip: To easily sort lists of pairs, you can use the itemgetter function (already imported in the program). Here's an example in the Python interactive interpreter: >>> from operator import itemgetter >>> foo = [("a",2),("b",3),("c",1)] >>> foo.sort(key=itemgetter(1),reverse=True) >>> foo [('b', 3), ('a', 2), ('c', 1)] Also, you can use list comprehensions to do operations on all the elements of a list of pairs without for loops, e.g.: >>> bar = [(x[0],x[1]*2) for x in foo] >>> bar [('b', 6), ('a', 4), ('c', 2)] Problem 3 - Prepositional Phrase Attachment and smoothing [25 pts]Prepositional
phrase attachment is the well-known task of resolving a common
ambiguity in English syntax regarding whether a prepositional phrase
attaches to the verb or the noun in sentences with the pattern Verb Noun_Phrase Prepositional_Phrase. An example is I saw the man with the telescope.
If the prepositional phrase attaches to the verb, then the seeing was
done with the telescope; if it attaches to the noun, it indicates that
the man had the telescope in his possession. A clear difference can be
seen with the following related examples:
For this problem, you will use a conveniently formatted data set for prepositional phrase attachment which has been made available by . You can find it in the directory classify/data/ppa. Go to that directory and list the contents. There are three files which you will use for this problem: training, devset, and test. Look at the contents of training: classify/data/ppa/training 0 join board as director V 1 is chairman of N.V. N 2 named director of conglomerate N 3 caused percentage of deaths N 5 using crocidolite in filters V ... Each row lists an abbreviated form of a prepositional phrase attachment. The first item is just a source sentence‘ identifier that we can ignore. The four words correspond to the head verb, head noun, preposition, and head noun object of the preposition, in that order. The final element indicates whether the attachment was to the verb (V) or to the noun (N). For example, for the two spaghetti eating sentences given above, the abbreviated forms would be: 4242 ate spaghetti with meatballs N 4243 ate spaghetti with chopsticks V For this exercise, you will build a classifier that learns a model from the data in training and use it to classify new instances. You will develop your model using the material in devset. You must not personally inspect the contents of test — you will run your classifier on test only once, when you are done developing. The first thing you must do is produce features from the ppa data in the format used previously for the tennis problem. Each of the four columns in the ppa data implicitly indicates a separate attribute – let’s call them verb, noun, prep, and prep_obj, respectively. To begin, we'll just create features that are based directly on the attributes and their values. So, a line like, 0 join board as director V becomes the following: verb=join,noun=board,prep=as,prep_obj=director,V The program ppa_features.py reads in a ppa file and produce the features in the above format. Using this program, produce files for training and development as follows: $ mkdir out $ ./ppa_features.py --input data/ppa/training > out/ppa.basic.train $ ./ppa_features.py --input data/ppa/devset > out/ppa.basic.dev $ ./ppa_features.py --input data/ppa/test > out/ppa.basic.test You can run tennis_cat.py on the feature files that are produced and score the output with score.py: $ ./tennis_cat.py -t out/ppa.basic.train -p out/ppa.basic.dev | ./score.py -g out/ppa.basic.dev Accuracy: 67.39 Ratnaparkhi et al (1994) obtain accuracies of around 80%, so we clearly should be able to do much better. One obvious problem shows up if you look at the actual output: $ ./tennis_cat.py -t out/ppa.basic.train -p out/ppa.basic.dev | more V 0.832766613303 N 0.167233386697 V 1.0 N 0.0 V 1.0 N 0.0 V 1.0 N 0.0 V 1.0 N 0.0 N 0.5 V 0.5 V 1.0 N 0.0 V 1.0 N 0.0 N 0.5 V 0.5 V 1.0 N 0.0 V 0.999803237929 N 0.000196762070993 V 0.999826549526 N 0.000173450474426 V 0.999763228 N 0.000236771999789 V 1.0 N 0.0 V 1.0 N 0.0 There are many items that have zero probability for N, V, or both (those are the ones with uniform .5 probability for both labels). The problem is that we haven't done any smoothing, so there are many parameters that we assign zero to, and then the overall probability for the class becomes zero. For example, the tenth line in out/ppa.basic.dev is: verb=was,noun=performer,prep=among,prep_obj=groups,N The output gives zero probability to N because the only training instance that has noun=performer is with the V label: verb=juxtapose,noun=performer,prep=with,prep_obj=tracks,V Thus, the value of P(Noun=performer | Label=V) is zero, making P(Label=V | Verb=juxtapose, Noun=performer, Prep=with, PrepObj=tracks) also zero, regardless of how much the rest of the information looks like a V attachment. We can fix this by using add-λ smoothing. For example, we can smooth the prior probabilities of the labels as follows: 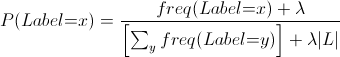 Part (a) [5 pts]. Written answer. Provide the general formula for a similar smoothed estimate for P(Attribute=x|Label=y) in terms of the relevant frequencies of x and y and the set ValuesAttribute consisting of the values associated with the attribute. (For example, ValuesOutlook from the tennis example is {sunny,rainy,overcast}.) If it helps, first write it down as the estimate for a specific parameter, like P(Outlook=sunny|Label=yes), and then do the more general formula. Part (b) [20 pts]. Implementation. Copy tennis_cat.py to ppa_cat.py, then modify ppa_cat.py to use add-λ smoothed estimates of the parameters. You have less explicit code guidance on this, so you need to create and populate the appropriate data structures for storing the set of possible values associated with each attribute. Note: the --lambda option has been set up for specifying the lambda value on the command line. The value is accessible as options.lambda_value. It has a default of 0, so if you do not specify a value for --lambda, the program should behave the same way that tennis_cat.py does (i.e, it should obtain the same accuracy). Use λ=1 while implementing and debugging this. You should obtain an accuracy of around 80% on the devset when you do the following: $ ./ppa_cat.py -t out/ppa.basic.train -p out/ppa.basic.dev -l 1 | ./score.py -g out/ppa.basic.dev Find a good λ for improving the accuracy on the development set. By exploring other values for λ, you may be able to improve the results. Written answer. Report the best λ you found and what accuracy you obtained. Tip. You can easily check many possible values for λ using the Unix command line. For example, $
for i in {0..10}; do echo $i; ./ppa_cat.py -t out/ppa.basic.train -p
out/ppa.basic.dev -l $i | ./score.py -g out/ppa.basic.dev; done You
should see multiple accuracy values go by, each one associated with the
λ value printed above it. (If this doesn't work, then you might not be
using the bash shell.) You can also specify ranges such as for i in .5 1 1.5 2 2.5 for drilling down further. Coding check. If you have implemented things correctly, you should get the following output for the tennis dataset: $
for i in {0..4}; do echo $i; ./ppa_cat.py -t data/tennis/train -p
data/tennis/test -l $i | ./score.py -g data/tennis/test; done 0 Accuracy: 61.54 1 Accuracy: 61.54 2 Accuracy: 69.23 3 Accuracy: 76.92 4 Accuracy: 76.92 Problem 4 - Computing with logarithms [15 pts]When
you calculated the values to determine the most probable label for
problems 1 and 2, you (probably) followed the equation directly and used
multiplication to combine the various probabilities. Doing so works
fine on small examples like those in problems 1 and 2, but ior problems 4
and 5 you will be using a much wider set of attributes
with even more values than those used so far. This means that you will
be combining a much larger group of much smaller probabilities, so you
might easily end up exceeding the floating point precision when many
more probabilties are to be combined. A straightforward way of getting
around this is to convert the probabilities to logarithms and use
addition of log probabilities instead of multiplication of
probabilities.First, here's a reminder of the basic property of interest: 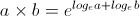 Try it out in Python: >>> import math >>> 6 * 7 42 >>> math.exp(math.log(6) + math.log(7)) 41.999999999999986 More generally: 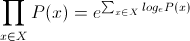 Thus, when determining the most probable label, we can do the following: 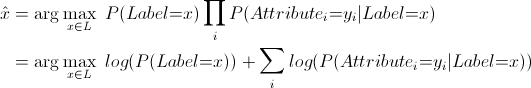 Part (a) [3 pts]. Written answer. Provide the formula for calculating P(yes|overcast,cool,normal,weak) when using log values of the parameters, such as logP(yes) and logP(no|yes). Note: you need to determine the probability, not the argmax. This is simple, but writing this out explicitly will help you for part (b). Part (b) [12 pts]. Implementation. Copy ppa_cat.py to log_cat.py, then modify log_cat.py so that the calculations are done using logarithms. Make sure that your modified version produces the same results on the tennis data and the ppa data as the original did, including when λ≠0. Keep in mind that:
Note.
You can do logs in various bases; which base you use doesn’t matter, as
long as you use it consistently. The easiest thing to do would be to
use math.log(number), which gives you base e. You can get other bases by providing an extra argument. For example, math.log(8,2) returns log28, the value 3.0. Note. Since working in log space involves addition and since the log of zero is undefined, unseen events don’t directly produce a probability of zero. You can nonetheless simulate this by having unseen features contribute a large negative amount, such as -50, to the calculation. Problem 5 - Extending the feature set [20 pts]The simple set of features used for the ppa data above can definitely be improved upon. For example, you couldhave features that:
Written answer. Describe five of the features you added, and why you think they would be useful. Tip. Some resources have been imported for you:
$ ./ppa_features.py -i data/ppa/training -e -b data/ppa/bitstrings > out/ppa.extended.train $ ./ppa_features.py -i data/ppa/devset -e -b data/ppa/bitstrings > out/ppa.extended.dev $ ./log_cat.py -t out/ppa.extended.train -p out/ppa.extended.dev -l 1 | ./score.py -g out/ppa.extended.dev Notice that the above commands use the shortened versions of the options. As before with the basic features, find an optimal λ on the dev set with the extended features. (Note that this may change as you add more features.) When you are satisfied that you cannot improve the performance any further, you can finally try out the test set! (Once you've done this, there is no going back to change the features any more.) Written answer. What is the performance you obtain when using the basic features and the extended features, each with their best λ? Note 1Keep in mind that it is possible to have the same attribute occur more
than once in a given instance, so your code should handle this. What
this means is that to get P(a=v|l), you do not divide by the frequency
of l, but by the overall frequency of a and l occurring together. This
will give you the same value for the tennis data and the ppa data
*before* you add your own features. In general, we can have lots instances of the same attribute with text classification -- for example, with twitter sentiment analysis, you will have tweets like:
With a positive sentiment. This will turn into a set of attribute-values + label like:
For smoothing the P(attr=val | label) distributions, you should not use
the length of the al_freq map (the keys of that map) in the
denominator. Remember that you are smoothing so that you can get a
non-zero value for *every* setting of attributes with the values for
*every* label. So, what you want is: for each attribute, collect the set
of *all* values that have occurred with it (*regardless* of the label),
plus one for the "unknown" value. Copyright 2011 Jason Baldridge The text of this homework is licensed under the Creative Commons Attribution-NonCommercial-ShareAlike License. Attribution may be provided by linking to www.jasonbaldridge.com and to this original homework. Please email Jason at jasonbaldridge@gmail.com with suggestions, improvements, extensions and bug fixes. |
Assignments >
